Download this assignment — unzip it, open homework-random-variables-and-moments.qmd in Positron, and answer inside the answer blocks.
$$ \newcommand{X}{} \newcommand{Y}{}
$$
Reminder: put each answer in its answer block. Working on paper is fine—photograph it and include it with  (image in the same folder as this file).
\[
\newcommand{\thetaprior}{\theta^{\text{prior}}}
\newcommand{\nprior}{n^{\text{prior}}}
\newcommand{\yprior}{y^{\text{prior}}}
\]
Warm-up: Computing Moments
Exercise 13.1 (One Deck, Two Sampling Mechanisms)
Draw three cards from a standard deck. Do every calculation twice: first replace and reshuffle each card before the next draw; then deal three cards without replacement. Let \(I_i\) indicate that card \(i\) is a heart, and let \(H=I_1+I_2+I_3\).
- Calculate \(\mathop{\mathrm{E}}[H]\) in both designs. Explain why the answer is the same even though only one design has independent indicators.
- Calculate \(\mathop{\mathrm{\mathop{\mathrm{V}}}}(H)\) with replacement by centering and squaring out the sum.
- Without replacement, calculate \(\mathop{\mathrm{E}}[I_1I_2]\) and compare it with \(\mathop{\mathrm{E}}[I_1]\mathop{\mathrm{E}}[I_2]\). Use the difference to calculate \(\mathop{\mathrm{Cov}}(I_1,I_2)\).
- Use the three variances and six ordered cross-terms to calculate \(\mathop{\mathrm{\mathop{\mathrm{V}}}}(H)\) without replacement. Which design is more precise, and where does the difference enter?
- Recover \(\mathop{\mathrm{E}}[H^2]\) in both designs from your means and variances.
- In each design, use Markov and Chebyshev to bound the probability of drawing three hearts. Then calculate the exact probability. What information does the exact calculation use that the two moment bounds discard?
Linearity does not require independence, so both designs have \[
\mathop{\mathrm{E}}[H]=\sum_{i=1}^3\mathop{\mathrm{E}}[I_i]=3\left(\frac{13}{52}\right)=\frac34.
\] With replacement, the indicators are independent and each has variance \(3/16\), so \(\mathop{\mathrm{\mathop{\mathrm{V}}}}(H)=9/16\). Without replacement, \[
\mathop{\mathrm{E}}[I_1I_2]=\frac{13}{52}\frac{12}{51}=\frac1{17},
\qquad
\mathop{\mathrm{E}}[I_1]\mathop{\mathrm{E}}[I_2]=\frac1{16},
\qquad
\mathop{\mathrm{Cov}}(I_1,I_2)=-\frac1{272}.
\] Consequently, \[
\mathop{\mathrm{\mathop{\mathrm{V}}}}(H)=3\left(\frac3{16}\right)+6\left(-\frac1{272}\right)
=\frac{147}{272}.
\] The negative covariances make dealing without replacement more precise. Finally, \(\mathop{\mathrm{E}}[H^2]=9/8\) with replacement and \(75/68\) without replacement. Markov gives \(P(H=3)\le1/4\). Since \(H=3\) is \(9/4\) above its mean, Chebyshev gives \(1/9\) with replacement and \(49/459\) without replacement. The exact probabilities are \((1/4)^3\) with replacement and \(\binom{13}{3}/\binom{52}{3}\) without replacement.
Recognition
Exercise 14.1 (What Is Independent?)
For each pair, say whether the two random variables are independent and identify the random mechanism that makes your answer true.
- The numbers shown on two separately rolled dice.
- Two successive cards dealt from one shuffled deck.
- Two separate fair coin flips.
- Two odds-and-evens players who each flip a separate independent fair coin.
- Two odds-and-evens players when the second player copies the first.
- The sum of two dice and the number on the first die.
- The two die results are independent when the dice are rolled separately.
- Successive cards from one shuffled deck are not independent: after the first card is known, the probabilities for the second card change.
- The two separate fair coin flips are independent.
- The players’ choices are independent because they use separate independent coins.
- The second player’s choice equals the first player’s choice, so the choices are dependent even though each player’s marginal distribution can look fair.
- The sum of the two dice and the first die are not independent. For example, if the sum is two, then the first die must be one.
Same Move, Many Surfaces
Exercise 15.1 (Variance of a Sum, the Conventional Way)
Let \(Y_1 \ldots Y_n\) be independent random variables with means \(\mu_1 \ldots \mu_n\) and finite variances.
- Center \(\sum_iY_i\), square out the centered sum, and take expectations term by term.
- Explain exactly where independence is used and why every off-diagonal term is zero.
- Conclude that \(\mathop{\mathrm{\mathop{\mathrm{V}}}}(\sum_iY_i)=\sum_i\mathop{\mathrm{\mathop{\mathrm{V}}}}(Y_i)\).
- Compare this proof with the independent-copy proof from class. Which step is genuinely different, and which algebra merely appears in a different place?
- If \(A,B,C\) are independent, use the operational rule for independence to explain why \(A+B\) and \(C\) are independent.
Writing \(Z_i=Y_i-\mu_i\), \[
\begin{aligned}
\mathop{\mathrm{\mathop{\mathrm{V}}}}\left(\sum_iY_i\right)
&=\mathop{\mathrm{E}}\left[\left(\sum_iZ_i\right)^2\right]
=\sum_i\sum_j\mathop{\mathrm{E}}[Z_iZ_j]\\
&=\sum_i\mathop{\mathrm{E}}[Z_i^2]
=\sum_i\mathop{\mathrm{\mathop{\mathrm{V}}}}(Y_i).
\end{aligned}
\] For \(i\ne j\), independence implies \(\mathop{\mathrm{E}}[Z_iZ_j]=\mathop{\mathrm{E}}[Z_i]\mathop{\mathrm{E}}[Z_j]=0\). The independent-copy proof avoids centering by the mean, but it still squares out a sum and kills mixed terms. Finally, independence of \(A,B,C\) means that their joint distribution factors. Summing that factorization over all values of \(A\) and \(B\) with the same value of \(A+B\) shows that the joint distribution of \((A+B,C)\) factors. Therefore, for any functions \(f,g\), \(\mathop{\mathrm{E}}[f(A+B)g(C)]=\mathop{\mathrm{E}}[f(A+B)]\mathop{\mathrm{E}}[g(C)].\)
Indicator Counting (Cards)
The indicator-counting technique in this section follows Blitzstein and Hwang, Introduction to Probability, 2nd ed. (2019), Chapter 4.
Exercise 16.1 (Count Without Finding the Distribution)
Deal five cards from a shuffled standard deck without replacement.
- Let \(H\) be the number of hearts in the hand. Write \(H\) as a sum of five indicators.
- Use linearity to calculate \(\mathop{\mathrm{E}}[H]\). Why does the dependence among the five indicators not matter for this calculation?
- Repeat the calculation for the number of aces.
- Generalize both answers to a hand of \(k\) cards.
- Which corresponding variance calculation would require information that linearity alone does not provide?
For each card position \(i\), let \(I_i\) indicate that the card is a heart. Then the number of hearts is \[
H=\sum_{i=1}^5 I_i.
\] Each position contains a heart with probability \(13/52=1/4\), so linearity of expectation implies \[
\mathop{\mathrm{E}}[H]=\sum_{i=1}^5\mathop{\mathrm{E}}[I_i]=5/4.
\] The indicators are dependent, but linearity does not require independence. The same argument gives an expected ace count of \(5(4/52)=5/13\). For a hand of \(k\) cards, the expected counts are \(k/4\) hearts and \(k/13\) aces. Calculating either variance requires pairwise joint probabilities, because the squared sum contains products \(I_iI_j\).
Tell a Story
Exercise 17.1 (Tell a Story About a Joint Distribution)
The random pair \((A,B)\) takes values in \(\{1,2\}\times\{1,2\}\). Its joint probabilities are \[
P(A=1,B=1)=P(A=2,B=2)=\frac12,
\qquad
P(A=1,B=2)=P(A=2,B=1)=0.
\]
- Tell a concrete story whose random pair has this joint distribution.
- Calculate the marginal distributions of \(A\) and \(B\).
- Someone sees only the two margins and says both variables look fair. What did they miss?
- Give a second joint distribution with the same margins in which \(A\) and \(B\) are independent.
Flip one fair coin. If it is heads, set \((A,B)=(1,1)\); if it is tails, set \((A,B)=(2,2)\). Then each variable is uniform on \(\{1,2\}\): \[
P(A=1)=P(A=2)=P(B=1)=P(B=2)=1/2.
\] The margins hide the dependence: observing \(A\) determines \(B\). An independent joint distribution with the same margins assigns probability \(1/4\) to each of the four pairs in \(\{1,2\}\times\{1,2\}\).
Convergence in Probability
Now let’s think about another notion of convergence. If an estimator’s sampling distribution ends up in the right location (\(\text{bias} \to 0\)) with arbitrarily little spread (\(\text{variance} \to 0\)), then it makes sense that any draw from it will be close to the estimation target \(\mu\).
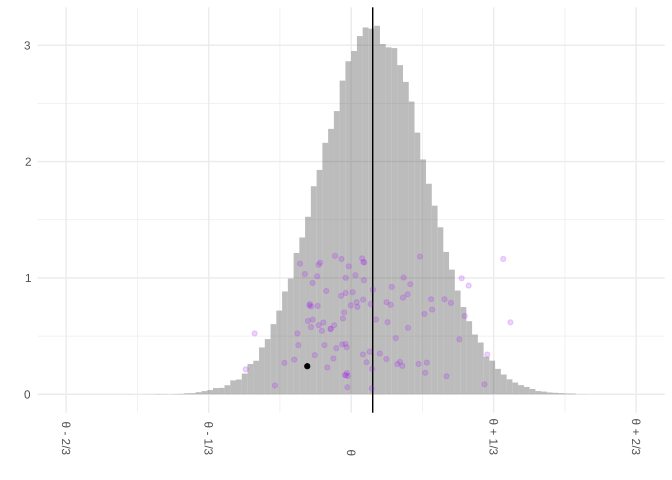
Recall that you can visualize your estimator as a single dot drawn from its sampling distribution. Like the black one below. And if you want to think of what happens if you were to repeat your survey 100 times, you can visualize the results by plotting 100 dots. Like the purple ones.
We formalize this idea by talking about convergence in probability. We say an estimator \(\hat\mu\) converges in probability to \(\mu\) if, for anyone’s idea of `sufficiently close’, the probability that \(\hat\mu\) is sufficiently close to \(\mu\) goes to one. Or equivalently, the probability that it isn’t sufficiently close goes to zero. \[
P(\lvert\hat\mu - \mu\rvert \ge \epsilon) \to 0 \qqtext{ as } n \to \infty
\]
Convergence in mean square implies convergence in probability. Let’s see why. We’ll use Markov’s inequality.
Markov’s Inequality
Markov’s inequality says that the probability a nonnegative random variable \(X\) exceeds some threshold \(t\) is bounded by the ratio of its expected value and \(t\), i.e., \[ P(X \geq t) \leq \frac{\mathop{\mathrm{E}}[X]}{t}\] Often, instead of using this to bound the random variable we’re interested in directly, e.g. \(X=\lvert\hat\mu - \mu\rvert\), we use it to bound its square. \(X \ge t\) if and only if \(X^2 \ge t^2\), so the probability that \(X \ge t\) is the same as the probability that \(X^2 \ge t^2\). Applying Markov’s inequality to the random variable \(X^2\) gives us a bound in terms of \(X\)’s mean square. \[
P(X \ge t) = P(X^2 \ge t^2) \leq \frac{\mathop{\mathrm{E}}[X^2]}{t^2} \qqtext{ e.g.}
P(\lvert\hat\mu - \mu\rvert \ge \epsilon) = P((\hat\mu - \mu)^2 \ge \epsilon^2) \leq \frac{\mathop{\mathrm{E}}[(\hat\mu - \mu)^2]}{\epsilon^2}
\]
This tells us, in terms of the mean squared error of \(\hat\mu\), how likely it is that \(\hat\mu\) is far from \(\mu\). And, in particular, it tells us that if the mean squared error goes to zero, then the probability that \(\hat\mu\) is any distance \(\epsilon\) away from \(\mu\) goes to zero.
Now we’re going to do two things. First, we’re going to prove Markov’s inequality. It’s good practice working with expectations and probabilities. Second, we’re going to look at what Markov’s inequality tells us about how close \(\hat\mu\) is to \(\mu\), i.e., we’re going to use it to calculate the coverage of an interval estimate.
First we define the following two functions, \(f\) and \(g\), with \(t, x\ge 0\). \[
f(x,t) = \frac{x}{t}
\] \[
g(x,t) = 1_{\ge t}(x) = \begin{cases}
1 & \text{ if } x \ge t \\
0 & \text{ otherwise }
\end{cases}
\]
Exercise 19.1
We pick \(t=3\), plot the two functions above on the same coordinate with \(x\) on the x axis. Based on the graph, what can we infer about the relationship between \(f(x,t)\) and \(g(x,t)\)?
It turns out that your inference is correct! For all \(t, x\ge 0\), \(\frac{x}{t} \ge 1_{\ge t}(x)\). Use the fact to prove Markov’s inequality.
Hint 1. \(\mathop{\mathrm{E}}[Y]\ge \mathop{\mathrm{E}}[Z]\) if \(Y\ge Z\)
Hint 2. Knowing that \(\frac{x}{t} \ge 1_{\ge t}(x)\), we can infer that \(\frac{X}{t} \ge 1_{\ge t}(X)\) for \(X\) being a non-negative random variable.
To see that \(u_t(x) = x/t \ge 1_{\ge t}(x)\) for all \(x \ge 0\), consider separately the cases \(x \ge t\) and \(x < t\). If \(x \ge t\), then \(1_{\ge t}(x)=1\) and \(x/t \ge 1\). If \(x < t\), then \(1_{\ge t}(x)=0\) and \(x/t \ge 0\). So \(u_t(x) \ge 1_{\ge t}(x)\) for all non-negative \(x\). It follows that for any non-negative random variable \(X\), \[
P(X \ge t) = \mathop{\mathrm{E}}[1_{\ge t}(X)] \le \mathop{\mathrm{E}}[u_t(X)] = \mathop{\mathrm{E}}\sb*{\frac{X}{t}} = \frac{\mathop{\mathrm{E}}[X]}{t}.
\]
Markov’s Inequality and Interval Estimation
So far, when we’ve calculated the coverage of an interval estimate in terms of its mean and variance, we’ve relied on normal approximation. That is, we’ve been using a different formula for \(P(\lvert\hat\mu - \mu\rvert \ge \epsilon)\) based on the idea that \(\hat\mu-\mu\) has approximately the same distribution as a normally-distributed random variable \(Z\) with the same mean—zero—and variance \(\sigma_{\hat\mu}^2=\mathop{\mathrm{\mathop{\mathrm{V}}}}[\hat\mu-\mu]\). We can use this approximation, in combination with our knowledge of the probability density of the normal approximation, to get a bound on the probability that \(\lvert\hat\mu - \mu\rvert \ge \epsilon\).
\[
P(\abs{\hat\mu - \mu} \ge \epsilon) \approx P(\abs{Z} \ge \epsilon) = 1-P(\abs{Z} < \epsilon) = 1- \int_{-\epsilon}^{\epsilon} f_{\sigma_{\hat\mu}}(z) dz \qfor f_{\sigma}(z) = \frac{1}{\sqrt{2\pi}\sigma} e^{-z^2/(2\sigma^2)}
\]
The reason we’re always talking about intervals of the form \(\hat\mu \pm 2 \sigma_{\hat\mu}\) is that, using this approximation, that yields 95% coverage. That is, \(P(\abs{Z} < 2 \sigma_{\hat\mu}) \approx .95\). To see why we tend to use normal approximation instead of Markov’s inequality, let’s see what Markov’s inequality tells us about how close an estimator is to its estimation target and about the coverage of this interval.
Exercise 19.2
To see what Markov’s inequality can tell us, first we can apply the property to the squared deviation from the mean:
\[
X = \{\hat{\theta}-\mathop{\mathrm{E}}[\hat{\theta}]\}^2
\]
\[
P(X\ge t)\le \frac{\mathop{\mathrm{E}}[\{\hat{\theta}-\mathop{\mathrm{E}}[\hat{\theta}]\}^2]}{t} = \frac{\mathop{\mathrm{\mathop{\mathrm{V}}}}(\hat{\theta})}{t}
\]
When we do this, what does Markov’s inequality tell us about how close our estimator is to its mean? What is the probability that it’s within 1, 2, 3 standard deviations?
We can use this to calibrate an interval. What does it tell us about the probability that \(\hat{\theta} \pm 2 \sigma_{\hat{\theta}}\) contains \(\mathop{\mathrm{E}}[\hat{\theta}]\)? How wide must an interval of width \(w\) be so that \(\hat{\theta} \pm \frac{w}{2}\) has 95% coverage?
Hint. \(\hat{\theta} \pm \frac{w}{2}\) contains \(\theta\) if and only if \(|\hat{\theta}-\theta| \le \frac{w}{2}\). Therefore, \(P(\hat{\theta} \pm \frac{w}{2} \text{ contains } \theta) = P(|\hat{\theta}-\theta| \le \frac{w}{2})\).
It tells us that the first interval has coverage probability at least \(1-1/4=.75\) and that, to get an interval for which it implies a coverage probability of at least .95, we need to make \(t=\sqrt{20}\approx 4.5\).
I didn’t ask for this here, but let me offer an interpretation. Where normality of our estimator’s sampling distribution would imply 95% coverage for the interval \(\hat\mu \pm 2\sigma_{\hat\mu}\), Markov’s inequality implies 75%. Where to get a 95% interval based on normality we’d use \(\hat\mu \pm 2\sigma_{\hat\mu}\), to get a 95% interval based on Markov’s inequality we’d use \(\hat\mu \pm 4.5\sigma_{\hat\mu}\)—an interval over twice as wide. That’s why we don’t use Markov’s inequality for much if we have a better alternative, e.g., if normal approximation is justified or we can use the bootstrap. It’s not wrong, but what we can say based on it is more conservative than what we can say based on other techniques.
Comparing Interval Calibration Methods
Exercise 20.1 (Exact and Guaranteed Intervals)
Return to the binary population and sample size from the earlier calibration homework. Use the exact Binomial method from that homework and the Chebyshev method from this week’s chapter.
- Derive the value \(t\) for which Chebyshev guarantees \(P(|\hat\theta-\theta|\le t\sigma)\ge .95\).
- On the same axis, draw the exact middle-95% interval for \(\hat\theta\) and the guaranteed interval \(\theta\pm t\sigma\).
- Compare their widths over a grid of values of \(\theta\). Which method needs the full distribution, and which needs only the first two moments?
- Explain why the guaranteed interval is useful even though it is much wider.
- Save this comparison. After normal approximation, add the normal interval to the same object rather than starting a new exercise.
Chebyshev’s inequality states \[
P\left(\left|\hat\theta-\theta\right|\ge t\sigma\right)
\le \frac{1}{t^2},
\] where \(\hat\theta\) is the sample proportion and \(\sigma\) is its standard deviation. Setting \(1/t^2=.05\) implies \(t=\sqrt{20}\). Therefore the guaranteed middle interval is \[
\theta\pm\sqrt{20}\,\sigma.
\] The exact interval is obtained from the middle 95 percent of the Binomial law used in the earlier calibration homework. It is narrower because it uses the full distribution. The Chebyshev interval uses only the first two moments and is valid without assuming a particular distributional shape. That is why the guarantee remains useful even when it is loose.
Exercise 20.2 (Coverage Is an Empirical Question)
Let \(\theta=.7\) and draw binary samples of size \(n=625\). For each sample, calculate both the sample mean \(\bar Y\) and the pseudo-observation estimator \(\tilde Y_{\nprior}\) from Exercise 18.2 with \(\nprior=100\) and \(\thetaprior=.5\).
- For each estimator, construct three intervals centered at the observed point estimate: a 95% bootstrap interval, a 95% normal-approximation interval, and an interval whose radius is \(\sqrt{20}\) times the estimated standard deviation. For the pseudo-observation estimator, estimate its standard deviation by replacing \(\theta\) with \(\bar Y\) in the variance formula you derived earlier. The last radius is Chebyshev-calibrated around the estimator’s expectation; for the biased estimator, it does not guarantee 95% coverage of \(\theta\).
- Repeat the experiment 1,000 times. For each of the six estimator-and-calibration pairs, report empirical coverage and average width.
- Which calibration method would you use for each point estimator? Separate the question “is the interval narrow?” from “does it cover \(\theta\) 95% of the time?”
- Repeat with \(n=2500\). Explain why increasing the amount of real data changes both the bias and the variance advantage of the pseudo-observations.
The following code uses symmetric intervals centered at each observed point estimate. The bootstrap radius is the middle 95 percent of the absolute bootstrap deviations from that estimate.
The Chebyshev-calibrated intervals are much wider than the normal and bootstrap intervals. For the sample mean, that width buys a distribution-free bound when the true variance is used. For the biased estimator, the same radius controls departure from the estimator’s expectation, not departure from \(\theta\); the simulation therefore measures rather than assumes its target coverage.
Increasing \(n\) reduces the weight \(100/(100+n)\) placed on the pseudo-observations, so their bias shrinks. It also reduces their variance advantage over the sample mean. The comparison separates those two effects from the choice of interval calibration.
Exercise 20.3 (One More Moment)
Let \(X\) equal one with probability \(p\) and zero with probability \(1-p\).
- List the two possible values of \(|X-p|^3\) and their probabilities.
- Calculate \(\mathop{\mathrm{E}}|X-p|^3\).
- For \(n\) independent copies, calculate the sum of the \(n\) individual third absolute centered moments.
- The later normal-approximation result uses this sum. Why is that easier than calculating the distribution—or the third absolute centered moment—of the sum itself?
The two values of \(|X-p|^3\) are \((1-p)^3\) with probability \(p\) and \(p^3\) with probability \(1-p\). Therefore \[
\mathop{\mathrm{E}}|X-p|^3=p(1-p)^3+(1-p)p^3.
\] For \(n\) independent copies, the sum of the individual third absolute centered moments is \(n\) times this quantity. No distribution of a sum has been calculated.
Paley–Zygmund: The Other Half
Exercise 21.1 (Bonus: A Lower Bound on Spread)
For a nonnegative random variable \(Z\) and \(0<a<1\), the Paley–Zygmund inequality says \[
P(Z\ge a\mathop{\mathrm{E}}Z)\ge (1-a)^2\frac{(\mathop{\mathrm{E}}Z)^2}{\mathop{\mathrm{E}}[Z^2]}.
\] Let \(Y\) have mean \(\mu\), positive variance \(\sigma^2\), and finite fourth centered moment. Apply the inequality with \(Z=(Y-\mu)^2\) and \(a=1/2\).
- Rewrite the event \(Z\ge a\mathop{\mathrm{E}}Z\) as a statement about \(|Y-\mu|\) and \(\sigma\).
- Express the resulting lower bound using \(\sigma^4\) and \(\mathop{\mathrm{E}}[(Y-\mu)^4]\).
- Chebyshev says there cannot be too much probability far from \(\mu\). Explain how this result says that the standard deviation cannot be describing spread that is not really there.
Since \(\mathop{\mathrm{E}}Z=\sigma^2\) and \(\mathop{\mathrm{E}}[Z^2]=\mathop{\mathrm{E}}[(Y-\mu)^4]\), \[
P\left(|Y-\mu|\ge\frac{\sigma}{\sqrt2}\right)
\ge\frac{\sigma^4}{4\mathop{\mathrm{E}}[(Y-\mu)^4]}.
\] Chebyshev supplies an upper bound on distant tails; this supplies a lower bound on a standard-deviation-scale departure when the fourth moment is controlled.